A dated record of
what the page said
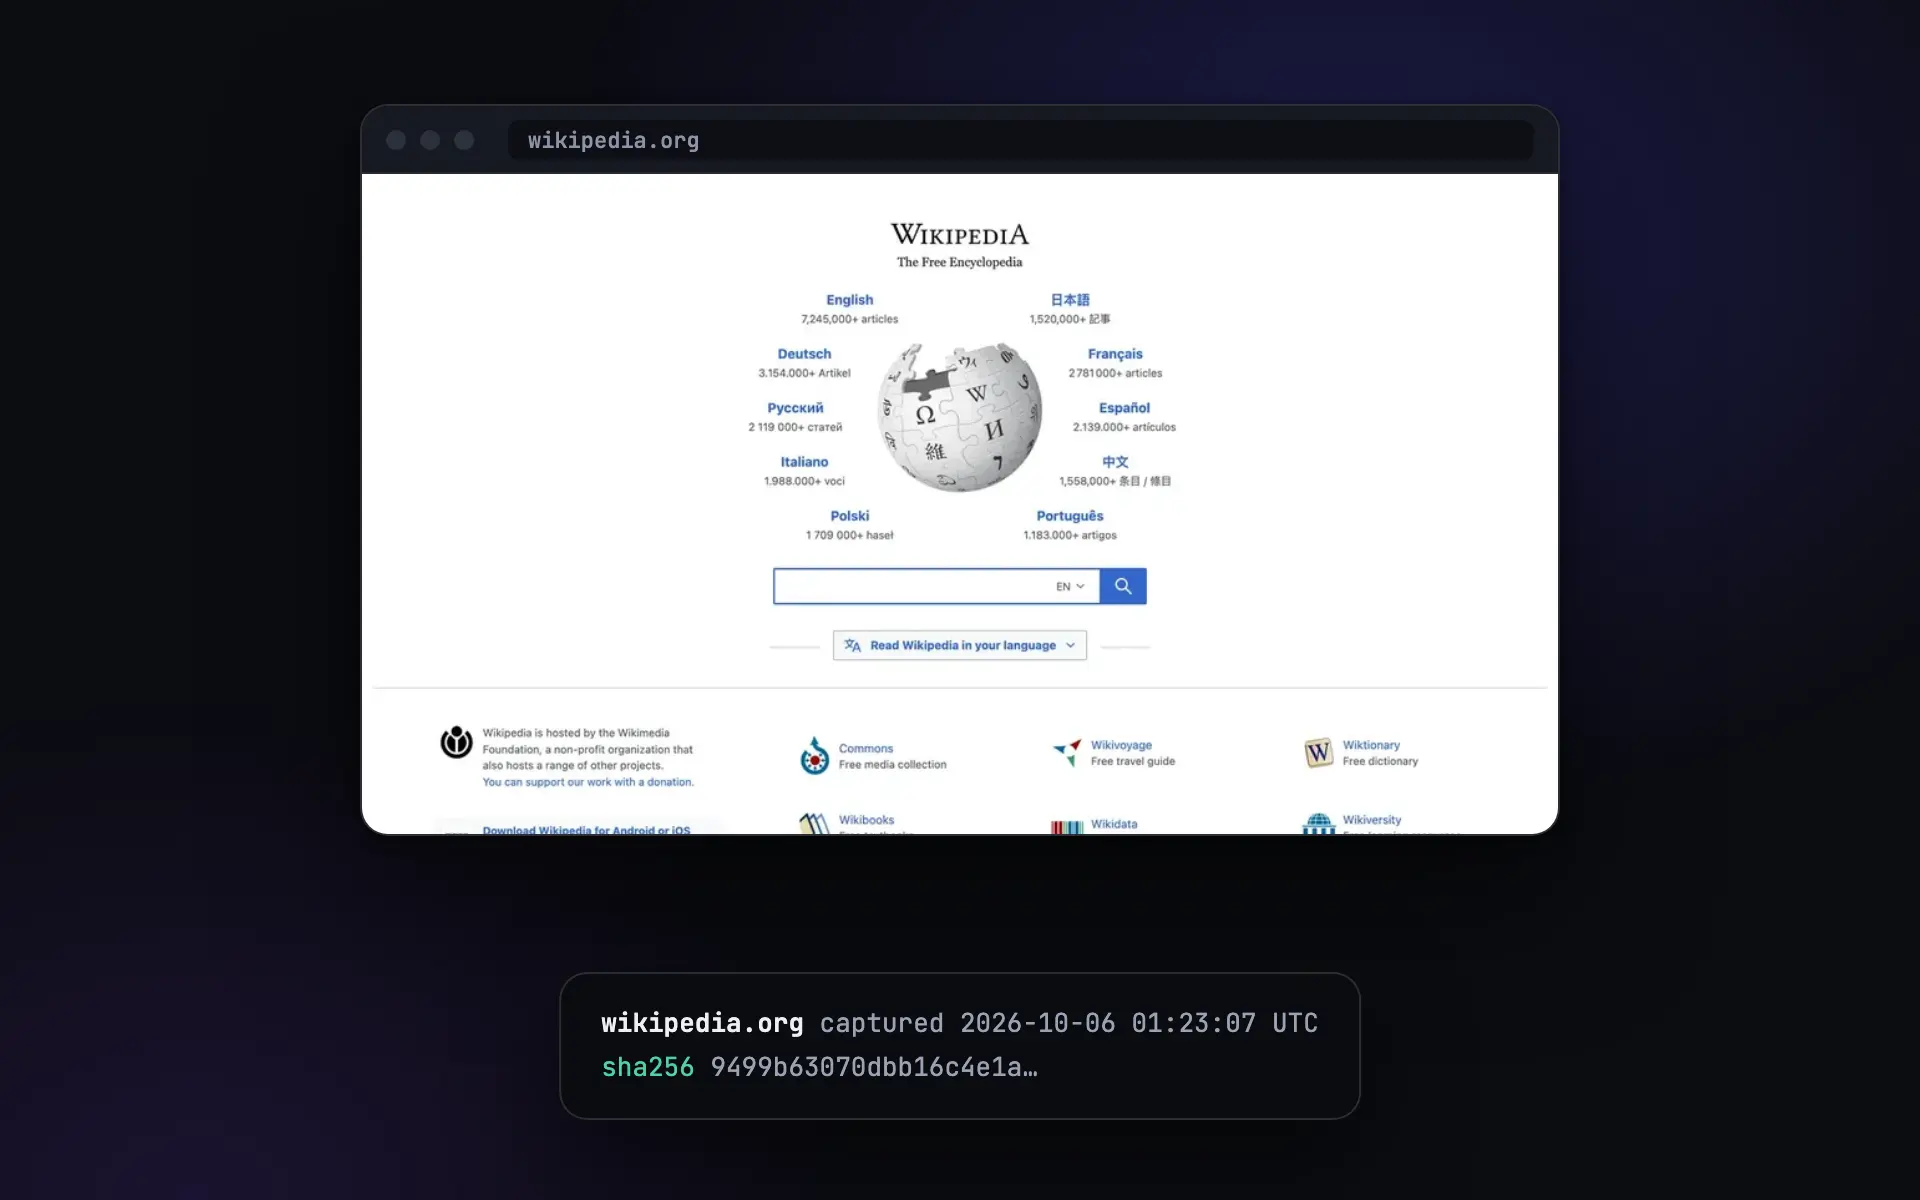
Add the pages you must keep a record of and SnapRender captures them on schedule: the full page as it rendered, dated, with a SHA-256 hash, kept for up to 180 days. Cookie banners are removed, so the record shows what your users actually read.
200 renders a month free, no card. Every feature on every plan.
Two ways to run it
Let SnapRender run the schedule, the comparison and the alerts, or call the API from your own code. Same captures, same price per render.
Without code: a schedule
Add each page you need a record of, daily or weekly, full page if you like
Every capture is stored as a dated PNG with its SHA-256 hash, for 7 to 180 days by plan
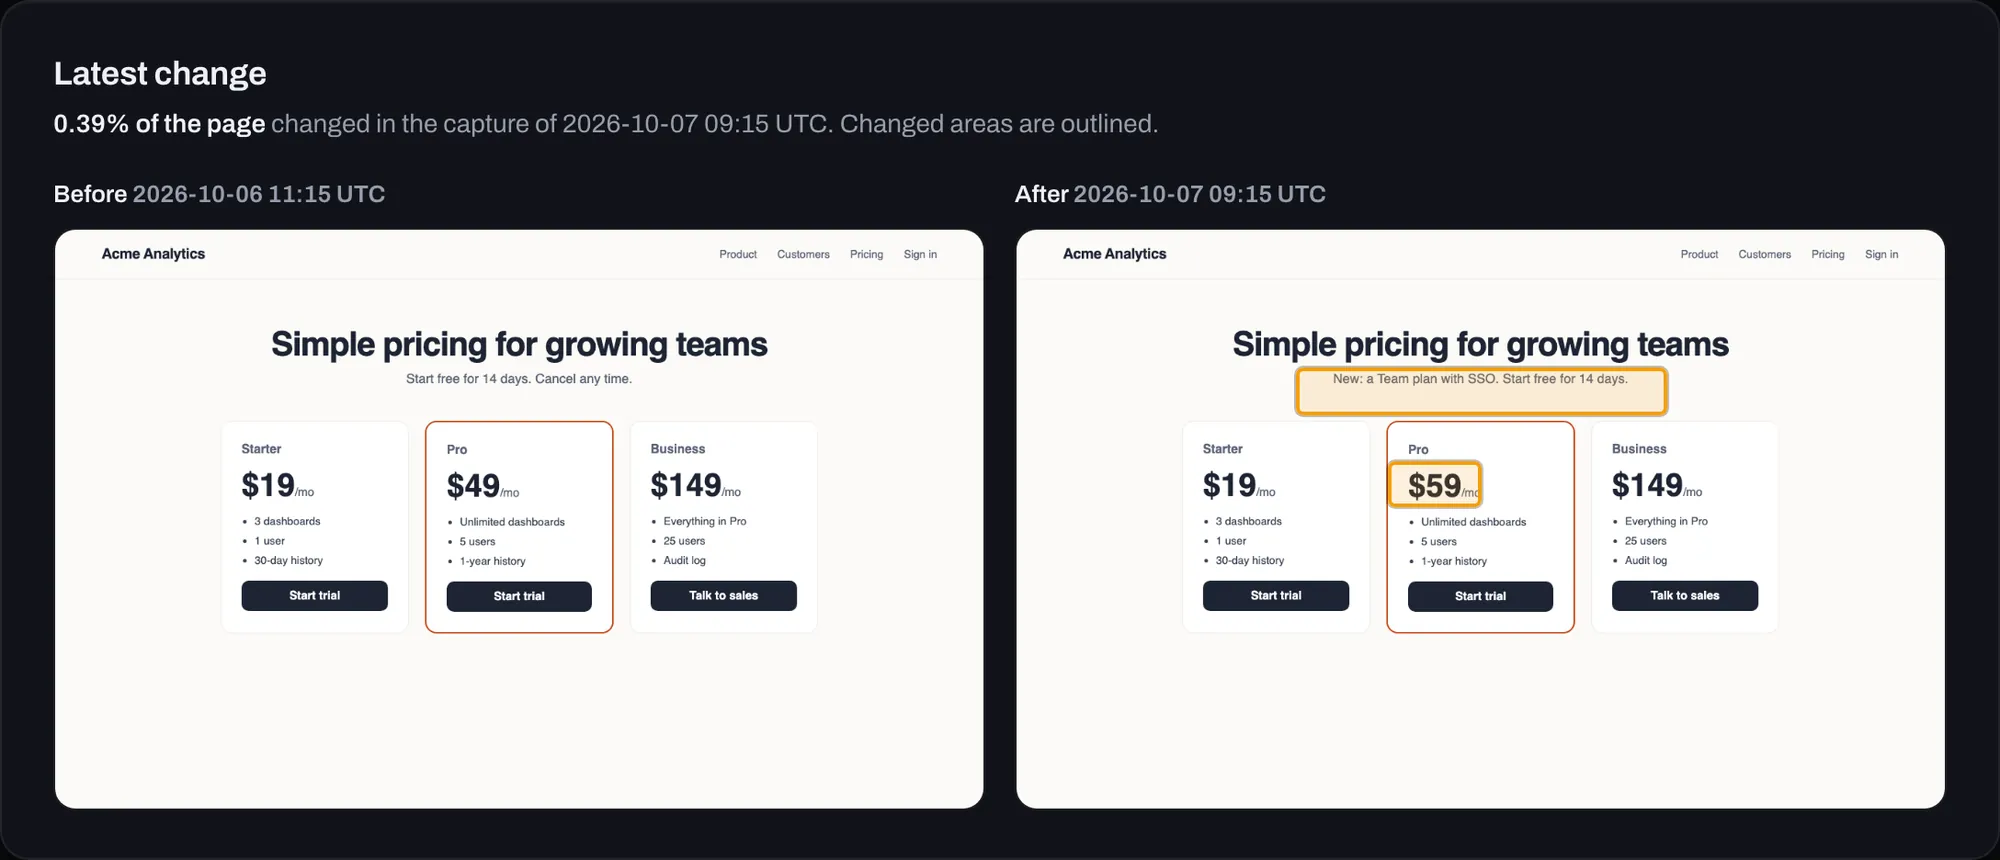
Download any version when someone asks what the page said, and get an alert when it changes
With code: the recipes below
The pattern is capture, hash, timestamp, store. Each step is a few lines, and the result is a file plus a JSON record that anyone can verify later by recomputing the hash.
- archive.py: capture, hash and record (Python)
- Independent timestamp (RFC 3161) (Shell)
- store.py: write-once storage in S3 (Python)
Try it on your URL
Live capture, no signup. You get the screenshot and the exact API call that produced it.
This is the exact API call that made the image above. Swap in your key and it runs anywhere.
200 renders a month free.
You hit the free demo limit here. The full tool can verify you are human and keep going.
Continue in the full toolWhy this is harder than it looks
Disclosures, pricing pages, terms of service and ad landing pages change without notice, and the question of what a page said on a given day usually comes up months later. By then the page has moved on and the only copies are whatever someone happened to save.
A screenshot taken by hand proves little. It has no reliable date, no hash, a consent banner across the middle, and it covers only the part of the page that fit on someone's screen. A record that has to stand up needs the whole page, a fixed capture time and a way to show the file was not edited afterwards.
Running that capture yourself means maintaining a headless browser that renders the full page reliably, including lazy-loaded sections. That is the part SnapRender takes off your hands. The record-keeping around it stays in your systems, under your retention rules.
Who does what
With a schedule, SnapRender does the capture, the history and the alert. With your own code, the schedule and the files stay in your systems.
SnapRender does
- Render the full page in real Chromium, lazy-loaded sections included, with cookie and consent banners removed
- Return PNG for an exact visual record or PDF for document workflows
- Render fresh on every request, so each capture reflects the page at that moment
- Capture up to 50 pages per batch call when a whole site section needs a snapshot
- Or capture on a schedule and record a SHA-256 and timestamp for every PNG (POST /v1/schedules)
You wire up
- Choose the pages and how often they are captured
- For records kept longer than 180 days, copy each capture into write-once storage under your own retention policy
- Decide what the record has to prove; a screenshot shows what rendered, not who saw it
The code
The pattern is capture, hash, timestamp, store. Each step is a few lines, and the result is a file plus a JSON record that anyone can verify later by recomputing the hash.
import hashlib, json, os, pathlib, datetime, requests

API = "https://app.snap-render.com"
HEADERS = {"X-API-Key": os.environ["SNAPRENDER_API_KEY"]}
OUT = pathlib.Path("evidence")
OUT.mkdir(exist_ok=True)

def capture(url: str, fmt: str = "png") -> dict:
    started = datetime.datetime.now(datetime.timezone.utc)
    r = requests.get(f"{API}/v1/screenshot", headers=HEADERS, timeout=120, params={
        "url": url, "format": fmt, "full_page": "true",
        "block_cookie_banners": "true", "block_ads": "true",
    })
    r.raise_for_status()
    digest = hashlib.sha256(r.content).hexdigest()
    stamp = started.strftime("%Y%m%dT%H%M%SZ")
    path = OUT / f"{stamp}-{digest[:12]}.{fmt}"
    path.write_bytes(r.content)
    record = {
        "url": url,
        "captured_at_utc": started.isoformat(),
        "sha256": digest,
        "bytes": len(r.content),
        "format": fmt,
        "file": path.name,
    }
    path.with_suffix(".json").write_text(json.dumps(record, indent=2))
    return record

print(capture("https://example.com/terms"))
The JSON record next to each file holds the URL, the UTC capture time and the SHA-256. Anyone can verify the file later by recomputing the hash.
# Ask a public timestamp authority to sign the file's hash.
# The .tsr response proves the file existed, unchanged, at that time.
openssl ts -query -data evidence/20261005T080000Z-3f2a9c1b7e4d.png \
  -sha256 -cert -out capture.tsq

curl -s -H "Content-Type: application/timestamp-query" \
  --data-binary @capture.tsq https://freetsa.org/tsr -o capture.tsr

# Verify later against the authority's certificates
openssl ts -reply -in capture.tsr -text
A timestamp from a third party means the capture time does not rest on your own clock. Keep the .tsr file with the image and its JSON record.
# The bucket needs Object Lock turned on (which requires versioning).
import datetime, boto3

s3 = boto3.client("s3")
retain_until = datetime.datetime.now(datetime.timezone.utc) + datetime.timedelta(days=365 * 7)

for name in ["20261005T080000Z-3f2a9c1b7e4d.png", "20261005T080000Z-3f2a9c1b7e4d.json"]:
    with open(f"evidence/{name}", "rb") as f:
        s3.put_object(
            Bucket="my-evidence-bucket",
            Key=f"captures/{name}",
            Body=f,
            ObjectLockMode="COMPLIANCE",
            ObjectLockRetainUntilDate=retain_until,
        )
In compliance mode nobody can overwrite or delete the object until the retention date, the account owner included. Set the period your policy requires.
Every parameter is in the API reference and the OpenAPI spec. Errors come back as { "error": { "code", "message", "status" } }; a 429 with QUOTA_EXCEEDED means the monthly allowance is used.
What it costs at your volume
Weekly full-page captures of 40 pages are about 175 renders a month, inside the free plan. Daily captures of 200 regulated pages are about 6,000 a month, which is Growth at $29. Business at $79 covers 50,000 for programs that archive whole sites.
About 0 renders a month
Free
A month counts as 30 days. Failed captures are refunded. Yearly billing on paid plans is ten months for twelve. All plans.
Get a key and run the first recipe today
Every script on this page works with a free key: 200 renders a month, every feature included, no card. Your first capture takes about two minutes.
Paid plans from $9 for 2,000 renders. Yearly billing is ten months for twelve. Failed captures are refunded.
Frequently asked questions
Can SnapRender capture the pages on a schedule?+
Yes. A schedule captures each page daily or weekly (hourly on paid plans), stores every capture as a dated PNG with its SHA-256 hash, and keeps it 7 to 180 days by plan. Download any version from the dashboard or the API.
Is a SnapRender screenshot legally admissible?+
Admissibility depends on your jurisdiction and your process, not on the tool alone. SnapRender gives you a faithful full-page capture at a known time. A hash, an independent RFC 3161 timestamp and write-once storage are what let you show later that the file was not changed. Ask your counsel what your process needs.
Should I archive as PNG or PDF?+
PNG is an exact visual record and the usual choice for evidence. PDF fits document management systems. SnapRender PDFs are a rendered image of the page, so the text in them is not selectable; if you also need the text, store the output of GET /v1/extract?type=text next to the image.
Are cookie banners in the capture?+
No. Consent banners are removed before capture by default, so the record shows the page content. If your policy requires capturing the banner itself, set block_cookie_banners=false.
Does SnapRender keep a copy of my captures?+
Scheduled captures are kept 7 to 180 days by plan, each with its SHA-256 hash. Single API captures are returned in the response and not archived, and batch download links last 24 hours. For longer retention, copy captures into your own write-once storage, which most compliance policies require anyway.
Can I capture pages behind a login?+
SnapRender captures public pages. Pages that need a session are out of scope, and so is geo-targeted rendering from a specific country.